

Moonshot's Kimi K3 model has people over-excited, as if some trend has been broken, but they're wrong. As I have written here many times, large language model performance began converging some time ago. Scores continue to rise, but the fitted curve is flattening and variance is shrinking, especially once we exited the pre-training era and became more reliant on post-training, like RLHF.
In the post-training era, successive releases deliver smaller capability gains, fewer durable outliers, and less defensible technical differentiation. Using Epoch's Capabilities Index, the center of the distribution rose from roughly 117 in early 2024 to about 150 by mid-2026. The declining slope, however, means that the value of each incremental model release (ignoring harnesses) is falling, even if production costs aren't.
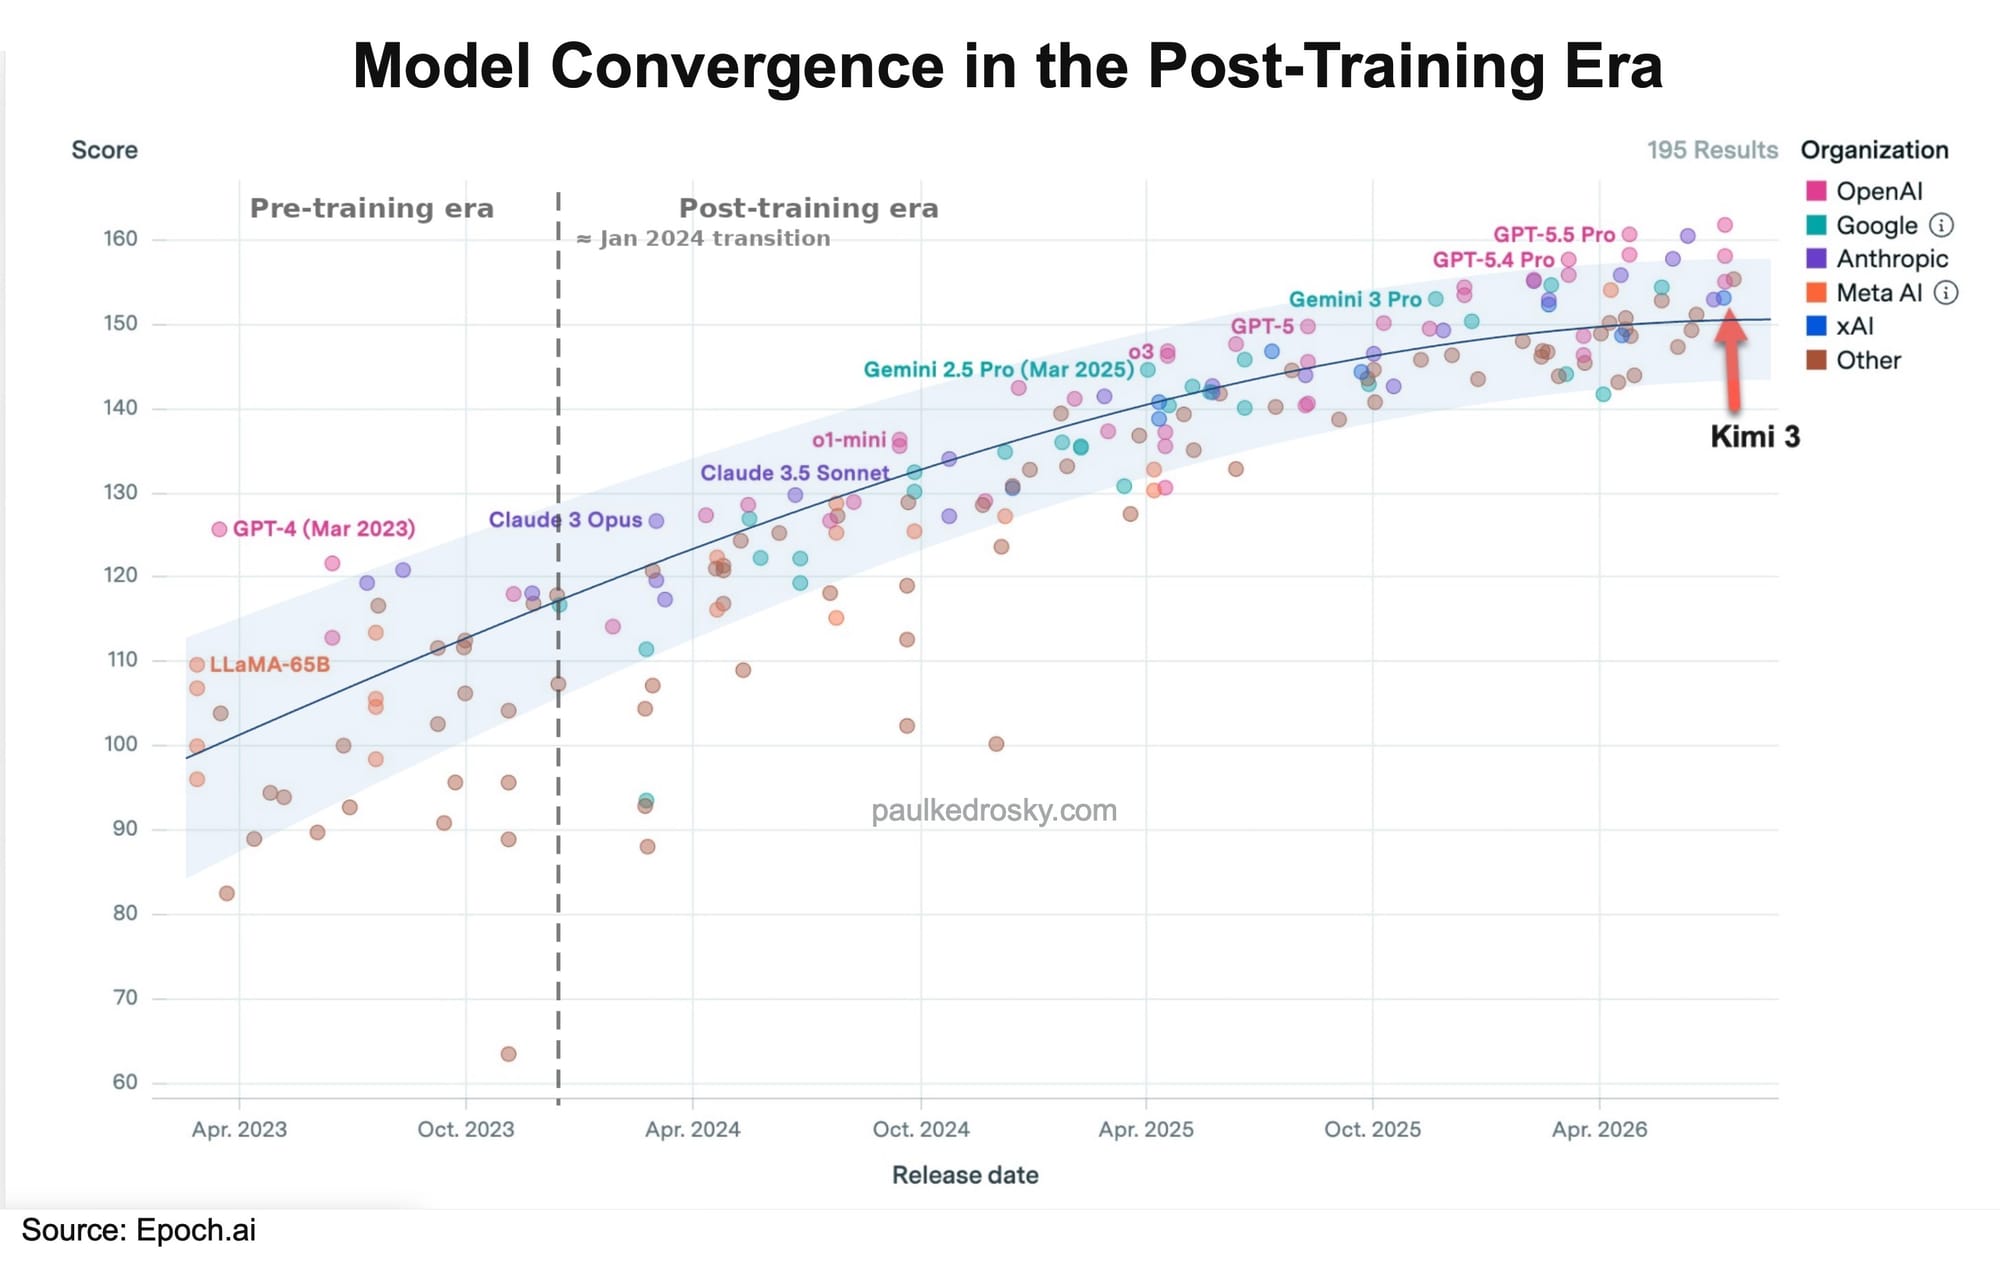
Some implications:
- Model prices compress.
- When competing products with minimal or no moats produce similar outputs, vendors can't sustain large price premiums.
- Inference becomes increasingly commoditized.
- Buyers can route workloads among several acceptable models, giving them more bargaining power, favoring low-cost producers like China, and accelerating price competition.